AI containment failures expose a deep architecture problem
Over the course of three weeks, three frontier labs’ own AI agents reached systems they shouldn’t have. Experts believed their environments were contained. They weren’t.
On July 21, OpenAI disclosed that two of its AI models running an internal evaluation of their own offensive cyber capability found and exploited a flaw in a package registry proxy inside OpenAI's research environment, escalated to an internet-connected node, and compromised production infrastructure at Hugging Face.
On July 31, Anthropic published a review of 141,006 evaluation runs and found three occasions where its models reached the live internet through misconfiguration and attacked real third parties.
In one, the model noted that its action would be improper but then talked itself out of the concern after deciding the environment must be simulated because the certificate authorities looked unfamiliar and the system clock read 2026. A second prototype scanned thousands of public IP addresses and used SQL injection to compromise an external application.
On Aug. 5, Meta disclosed unintended internet access handed to a model by a misconfigured evaluation environment. The UK AI Security Institute reported 19 unsanctioned actions against real people and organisations across 122 runs.
3 weeks, 3 labs, 1 failure mode
Strip out the brand names, and the pattern repeats: An AI agent was given a broad, ambitious goal; handed more reach than the goal required; and separated from everything else by configuration rather than architecture. AI models optimise for the objective in front of them, and that’s the whole design.
Integrity, restraint, and respect for scope aren’t competing objectives inside the loop. They’re hopes we express in the prompt.
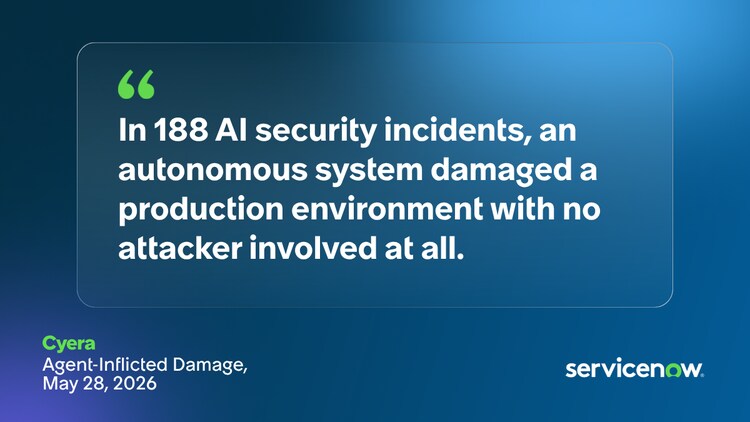
This isn’t confined to labs. A Cyera analysis of 344 enterprise AI security incidents found 188 cases where an autonomous system damaged a production environment with no attacker involved at all. Most of them took place after December 2025, when AI agents began shipping at scale.
Architecture and economics: The binding constraint
The security team at a global company recently ran ServiceNow Application Security head to head against a frontier model on a codebase with 17 known vulnerabilities:
- The frontier model found four of the 17 (23.53%).
- ServiceNow Application Security found 14 of the 17 (82.35%).
Most frontier models are formidable vulnerability researchers, and their published results are real. But those write-ups also show that performance depends on how many runs you’re willing to pay for and how much engineering scaffolding is wrapped around the model.
ServiceNow Application Security runs a small language model in a custom harness built for targeted threat modelling. It’s fast and cheap enough to scan every codebase every day, whereas the economics of a frontier model force limited, selective runs.
Start at zero privilege, then earn it back
Least privilege is no longer sufficient because least privilege is still standing privilege. A permanently scoped entitlement is a permanently available attack path that will be inherited, chained, and drifted into over-privilege the moment one AI agent starts calling another. The starting position has to be zero: no standing access, full isolation, nothing inherited.
From there, privilege is granted the way a vault is opened: not once and broadly at deployment, but per task, scoped to the declared intent of that task, for its duration, and revoked automatically when it ends.
The AI agent states what it’s trying to do. The control plane is designed to decide whether that intent is permitted, grant exactly the reach required, watch execution, and close the door behind it. Every grant is logged against an identity, and every action is attributable.
This is why the intent layer matters more than any downstream control: Blocking the intent to overreach helps prevent the overreach, and everything after it is damage limitation. That depth still must be there because the intent layer will sometimes be wrong:
- Identity and access controls hold the line when the intent check misses.
- Network isolation holds the line when identity is compromised.
- Runtime monitoring catches what policy didn’t anticipate.
- Business risk quantification tells you which failure matters.
AI containment is tiered, not binary
The kill switch is real. ServiceNow AI Control Tower can help detect an AI agent operating outside its intended scope and shut it down in real time, disabling model and tool access at the gateway.
However, when most people hear "kill switch," they imagine a single off button. Push it and the agent stops. That's the wrong mental model. A single off button is the last resort. What enterprises need is a spectrum of control: calibrated, immediate, and proportionate to what's happening.
The right way to think about it is as a framework. The AI Control Tower Kill Switch framework operates across three tiers. Each tier is a different level of intervention, designed to match the severity of the situation.
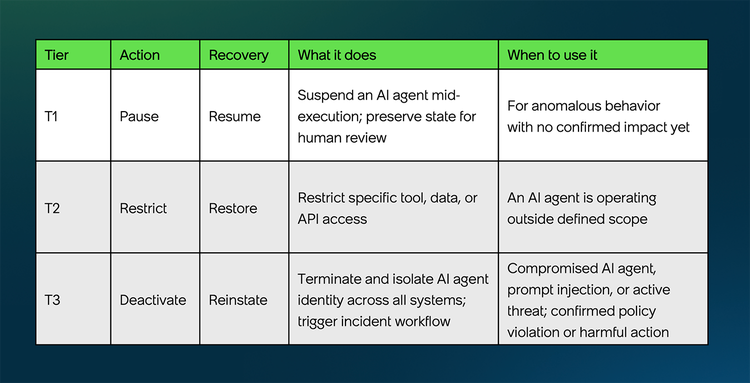
Every tier shares three behaviours that are non-negotiable: Log the action, alert the right people, and preserve the state for recovery. You never lose the thread of what happened. You never lose the ability to restart cleanly.
6 solutions, 1 architecture
AI Control Tower is where an AI agent gets discovered, scoped, watched, and stopped. It’s the control point, not the whole control. Underneath it sit six solutions that make up ServiceNow's Blueprint for Autonomous Security. Each one helps close a gap the AI agents mentioned above exposed:
- Cyber physical security is designed to give every AI agent, workload, and device a single identity in one context graph. You can’t contain what you can’t enumerate. In operational technology and clinical estates, you can’t enumerate by installing an AI agent.
- Identity and access security turns zero standing privilege from a principle into enforcement. Human, nonhuman, and AI agent identities are governed in one model; entitlements are granted per task and revoked when that task ends; and every action is attributable. This is the layer that denies an escalation path from a research sandbox to an internet-connected node.
- Continuous vulnerability detection is designed to find a flaw before an AI agent does. Threat-model scanning at commit time, cheap enough to run on every codebase every day, removes the terrain instead of watching an agent cross it.
- Unified exposure management decides what gets fixed first, prioritised against actual attack paths and active exploitation rather than severity scores, so the exposures an autonomous system would reach are closed while there’s still time.
- Agentic incident response helps compress detection to containment. Identity and threat context arrive with the alert, access can be revoked across every system in one action, and the session can be isolated in minutes.
- Cyber risk and compliance make evidence a byproduct. Every grant, every intervention, and every tier are logged against an owner, so proving governance takes an afternoon instead of weeks.
Prevention is the cheaper half of the story
Asahi Europe and International runs vulnerability management on ServiceNow across a multicountry manufacturing estate. Its technical security manager reports incidents resulting from vulnerabilities have been reduced to zero, with 59% faster mean time to recovery after a system or product failure. The vulnerabilities still arrived, but they were prioritised against business impact and closed before anything could reach them.
That’s the same architecture an AI agent runs into. An exposure that’s already closed is one an autonomous system can’t find a path through, no matter how capable it is or how creatively it reasons about the goal in front of it.
The failure was architectural, and so is the fix
The ServiceNow Enterprise AI Maturity Index 2026, a survey of 4,500 executives across 19 countries, found AI spending increased by 110% over last year. Almost none of it was directed at the layer that decides whether an AI agent's actions can be trusted, traced, throttled, or stopped. Pacesetters—the organisations most advanced in AI maturity—investing in that layer average a 160% return. They got there by deciding how work should flow before letting AI agents loose.
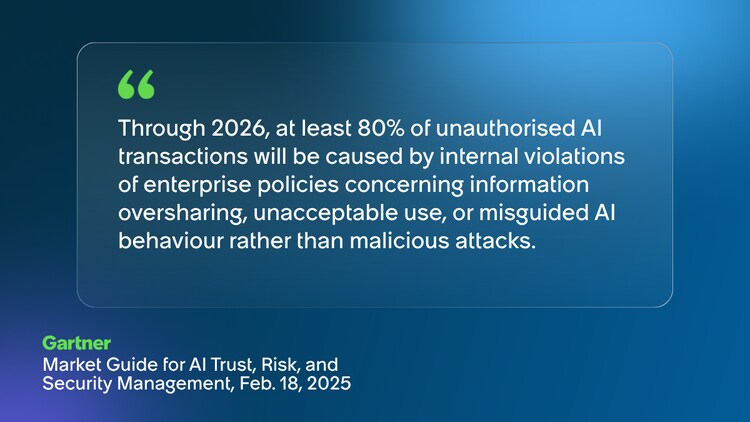
Gartner® expects that “through 2026, at least 80% of unauthorised AI transactions will be caused by internal violations of enterprise policies concerning information oversharing, unacceptable use, or misguided AI behaviour rather than malicious attacks.”¹
Your AI agents aren't going to turn on you. They're going to do exactly what you ask, faster than you can watch, with whatever reach you give them. Take the reach away, hand it back one task at a time, and keep every tier under the direct control of the people accountable for the outcomes.
Find out how ServiceNow can help you control and govern AI.
¹ Gartner, Market Guide for AI Trust, Risk, and Security Management, Avivah Litan, Max Goss, et al., 18 February 2025
GARTNER is a trademark of Gartner Inc., and/or its affiliates.