Multi-Modal Learning
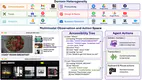
Web agents powered by large language and vision-language models are increasingly applied to realistic browser work that spans …
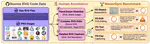
We introduce VectorGym, a new comprehensive multi-task benchmark for evaluating Vision-Language Models (VLMs) on Scalable Vector …
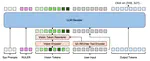
GUI grounding, the task of mapping natural-language instructions to pixel coordinates, is crucial for autonomous agents, yet remains …

Building reliable computer-use agents requires grounding: accurately connecting natural language instructions to the correct on-screen …
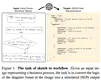
Workflows are a fundamental component of automation in enterprise platforms, enabling the orchestration of tasks, data processing, and …

Aligning visual features with language embeddings is a key challenge in vision-language models (VLMs). The performance of such models …
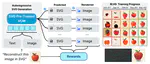
Scalable Vector Graphics (SVG) offer a powerful format for representing visual designs as interpretable code. Recent advances in …
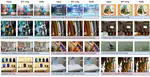
While image generation techniques are now capable of producing high quality images that respect prompts which span multiple sentences, …
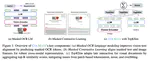
Retrieval-augmented generation has proven practical when models require specialized knowledge or access to the latest data. However, …
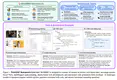
Understanding diverse web data and automating web development presents an exciting challenge for agentic multimodal models. While …